Domain AI you own
We build specialized models on open foundations, adapt them to your data, and run them where you choose. What’s trained on your data is yours.
General models know a little about everything. Your work needs one that knows what your people inspect, grade and decide every day, built on a foundation you choose.
Every field runs on expert calls: a look, a person, a judgment. Our models make those calls with your people, not instead of them.
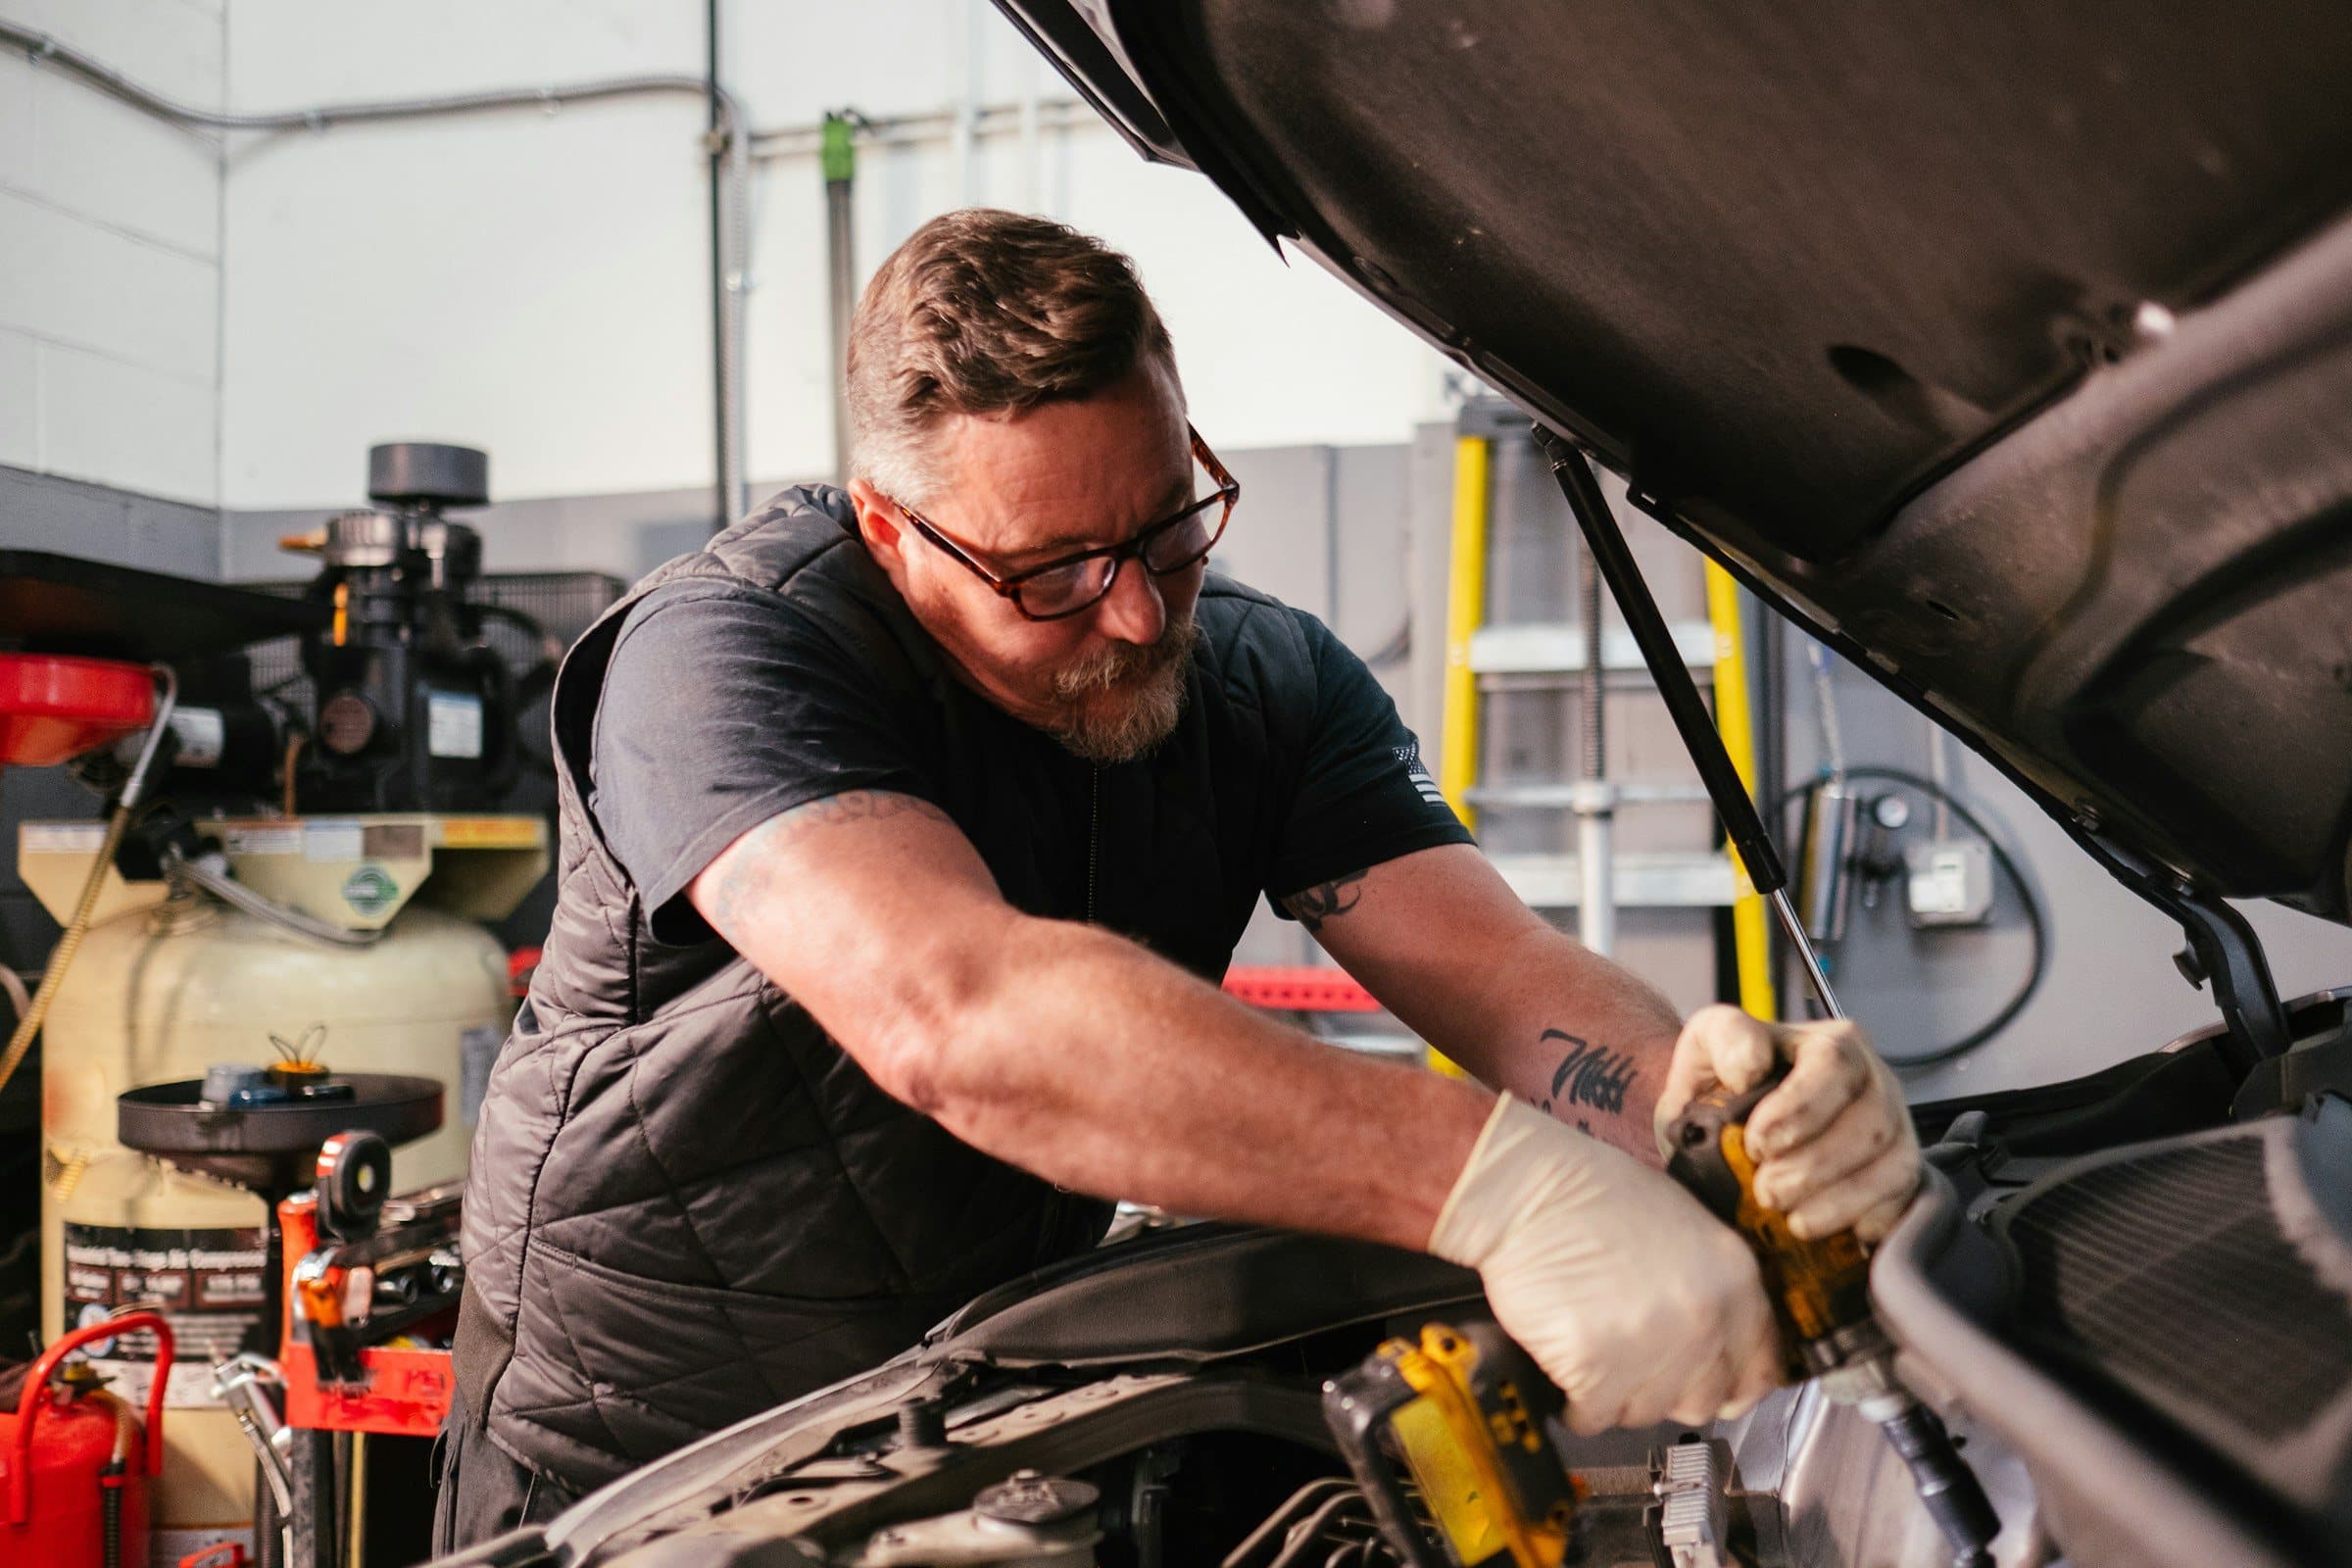
What a model you own is made of
Three layers. You choose the foundation, we build the domain model on it, and the layer trained on your data is yours. Scroll to split the stack.
Your choice
FoundationFoundation models
Built by Philotic
DomainPhilotic domain models
Owned by you
YoursYour layer
You choose one, we build one, you own one
Your choice
Foundation models
Vetted open-weight models with commercial licenses. You pick the one you’re comfortable with, by license, origin or size. We test the candidates on your task and show you the results.
Qwen3-VL-8B, Ministral 3 14B
Built by Philotic
Philotic domain models
Specialized models we build on top: curated, licensed data, labeling, evaluation and fine-tuning. This is the base intelligence for a domain, and it’s ready before your data arrives.
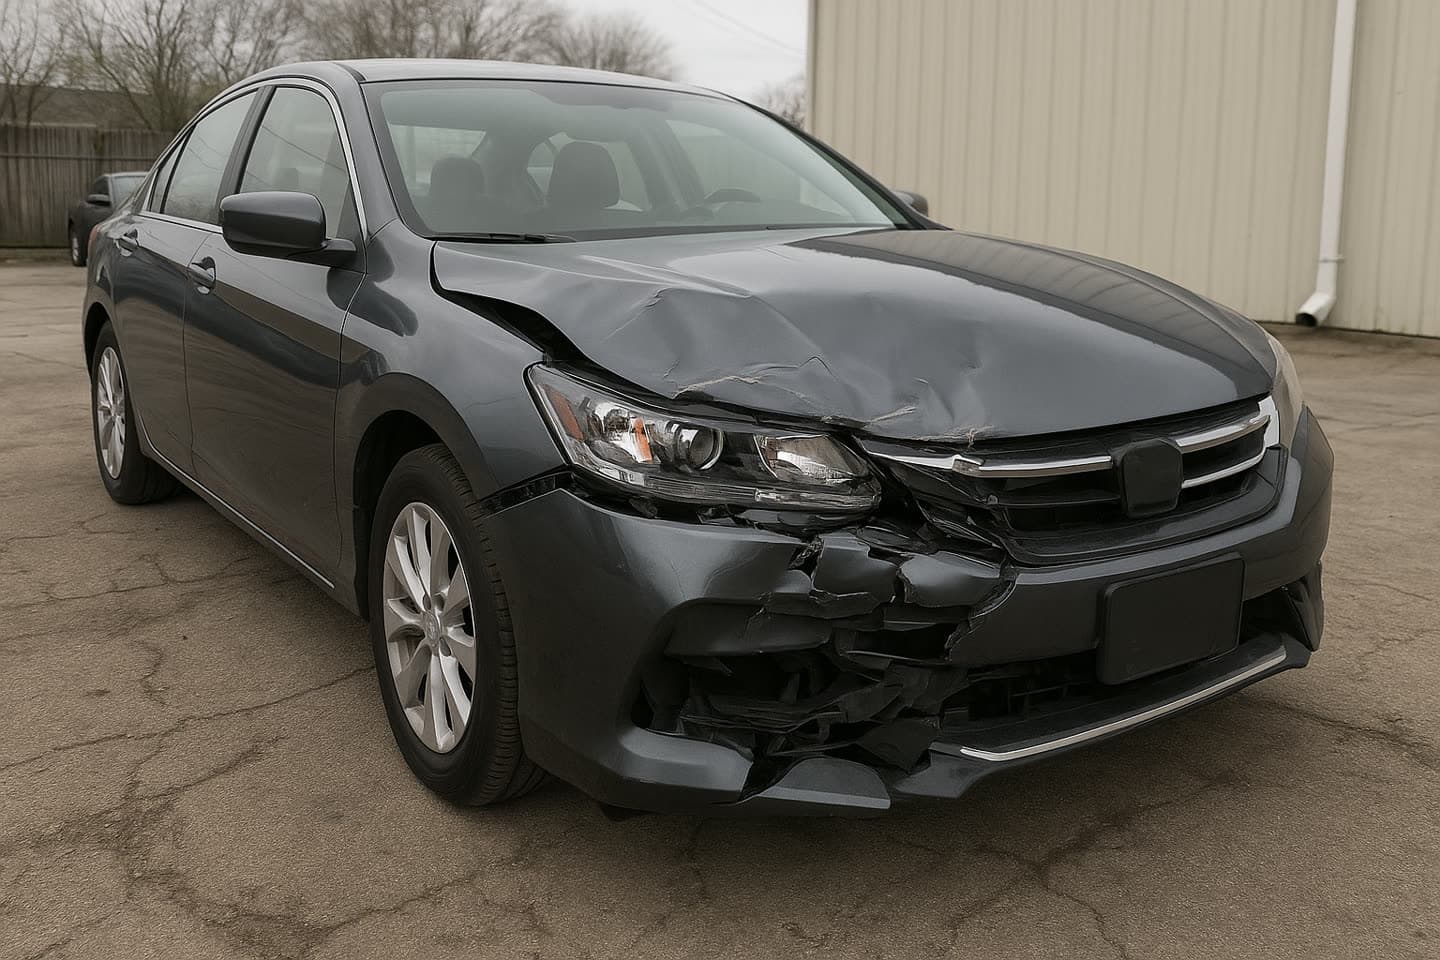
On 3,430 held-out areas, fine-tuning took damage-type accuracy from 25.7% to 78.7% on Ministral 3 14B, and from 53.8% to 80.8% on Qwen3-VL-8B.
Inspect, Grade
Owned by you
Your layer
Adapters trained on your own data and your people’s decisions. They’re separate weight files that belong to you outright, and they run wherever you choose.
Your labels, Your adapters, Your evaluations, Your conventions
On the record
Every result we publish is on held-out data, with its test-set size, against general models given the same question.
- Compared with
- Claude Sonnet 4.6
- Claude Opus 4.7
- Qwen3-VL-235B
- Foundations tuned
- Qwen3-VL-8B
- Ministral 3 14B
- Gemma 4 12B
- Held out
- 480 areas for damage type
- 194 areas for the part
- 200 whole photos
- 267 dents for severity
- 3,430 areas across foundations
- Published
- Introducing Philotic Inspect
- The foundation is your choice
Human judgment,built in
Our own labeling team writes the answers your model learns from and the tests it is judged on, to one standard per domain.
How it worksExperts on the hard calls
Severity and edge cases go to people who do the job, not an anonymous crowd.
appraisers, engineers, coaches
One standard per domain
A written guide, with agreement between reviewers measured on every batch.
guide, examples, agreement
Tests you can trust
Held-out sets are reviewed and frozen before any model is judged on them.
held out, reviewed, frozen
Your experts, your labels
Every accept or correction in your workflow becomes a label, and it belongs to you.
accept, correct, reject
Confidential by design
Your data is labeled only by your people, or by our vetted team with your written approval.
contract, approval, our tools
- Hosted in
- US regions
- Runs on
- Our hosting, your cloud or your servers
- Third-party model APIs
- None in customer builds
We host it, or you do
Every Philotic model runs on open weights and our inference code, so it can run where your data already lives: on capacity we dedicate to you, in your own cloud account, or on servers you own. AI stays off until a model passes an accuracy bar you approve, on held-out examples.
What’s built from your data is yours
| Yours | Your data, records and photos | Owned |
| Yours | Labels your people create | Owned |
| Yours | Labeled and evaluation sets | Owned |
| Yours | Adapters trained on your data | Owned |
| Licensed | Philotic domain models | For the term, with updates |
| Licensed | Inference code and containers | For the term |
| If you leave | Retrain on a foundation of your choice | Your call |
| If you leave | Buy out the version you run | Internal use |
| Ours | The platform and training pipeline | Never included |
One answer, one label
In Philotic Desktop, a model proposes and a person decides. Try it: answer the proposal in the middle.
Sample data, not a customer.
Proposed
Philotic Inspect · Item 4471 · Area 3
Crack on the housing
Your call
Philotic Inspect · Item 4471 · Area 3
Crack on the housing
Becomes a label
Philotic Inspect · Item 4471 · Area 3
Confirmed: crack on the housing
Your work, your model.
Tell us what your people inspect, grade or decide every day. We’ll test candidate foundations on your task and show you the results before anything goes live.